Deepfake Generalization
Aug 2026 to present
Overview
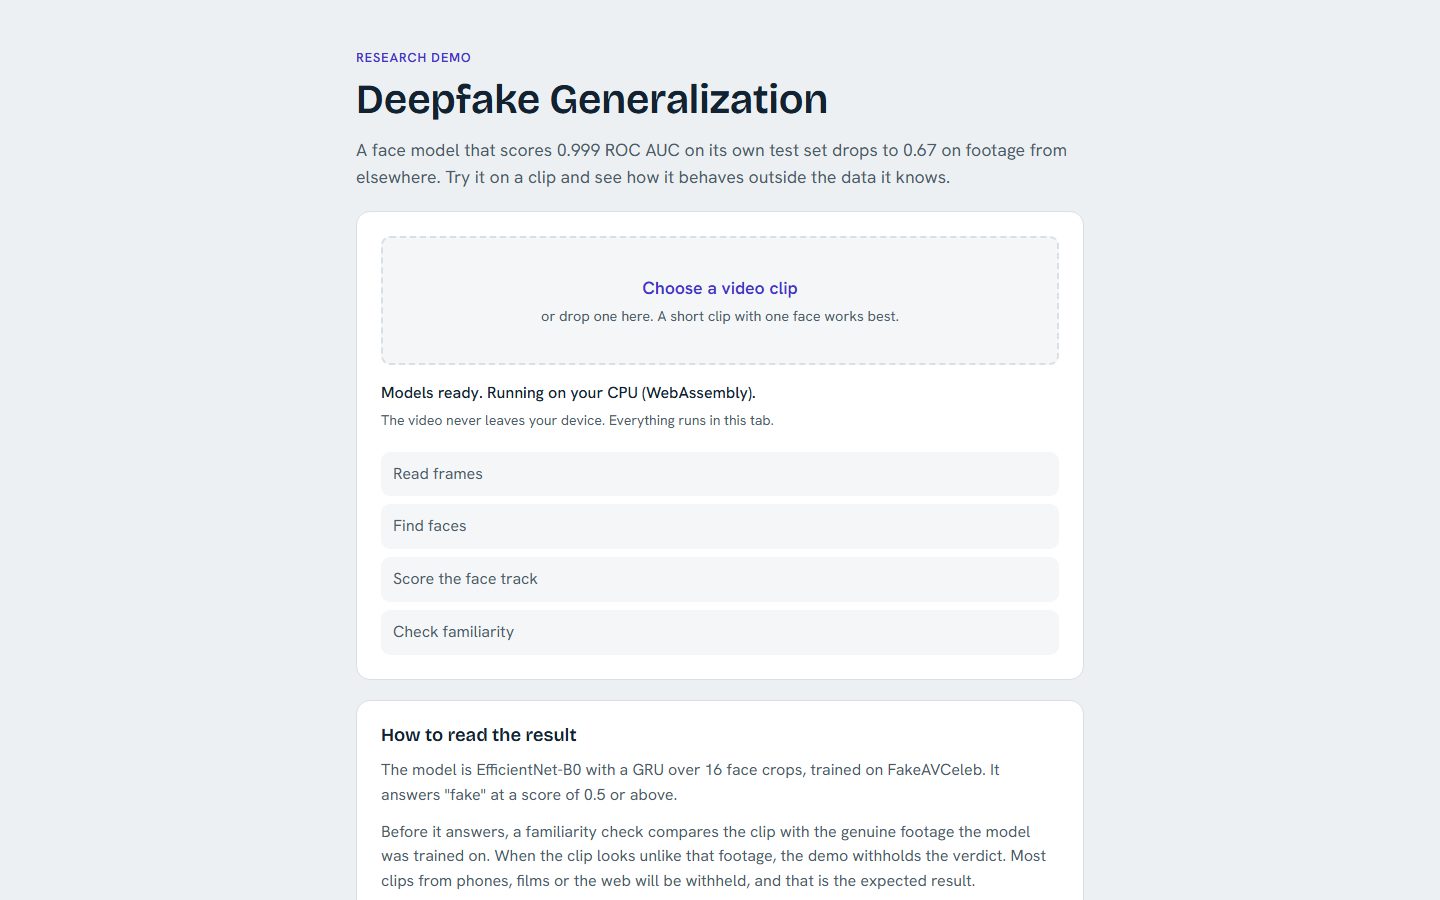
A face model that scores 0.999 ROC AUC on its own test set drops to 0.67 on Celeb-DF. This project studies that gap.
It tests whether three cue-specific detectors generalize better together than a visual detector alone. The branches inspect visual artifacts, audio spoofing, and mouth-audio alignment. Calibrated late fusion combines them, and the model withholds a verdict when required evidence is missing.
A second track asks whether a frozen encoder with a linear probe can detect a video generator it has never seen.
Findings So Far
Every measured claim lives in the repository's findings, and every number in the paper draft traces to a result row.
- In-domain scores are near perfect, and cross-corpus scores fall sharply.
- Earlier fusion comparisons found no cross-corpus gain. Their checkpoints used holdout labels to pick epochs, so that result needs a nested cross-fitting rerun.
- An earlier Perception Encoder score used the wrong input normalization, so its corrected performance is still unknown.
How It's Built
A Python package with a command line covers the whole pipeline, from metadata audits to training and reports.
- Data: source-disjoint splits of FakeAVCeleb, with identity-strict stress subsets and an audit of every split
- Faces: MTCNN detection with IoU tracking, and mouth crops for the lip-sync branch
- Models: PyTorch branches for faces, audio and lip sync, with runs tracked in MLflow
- Demo: the best face model, EfficientNet-B0 with a GRU over 16 face crops, exported to ONNX and run in the browser with WebAssembly
Interesting Challenges
- Knowing when not to answer: a familiarity check compares each clip with the genuine training footage. When a clip looks unfamiliar, the demo withholds the verdict
- Honest numbers: results that rest on a flawed protocol are marked as such and queued for a rerun, instead of being reported as wins
- Free hosting: the demo runs entirely in the visitor's browser, so it needs no GPU server